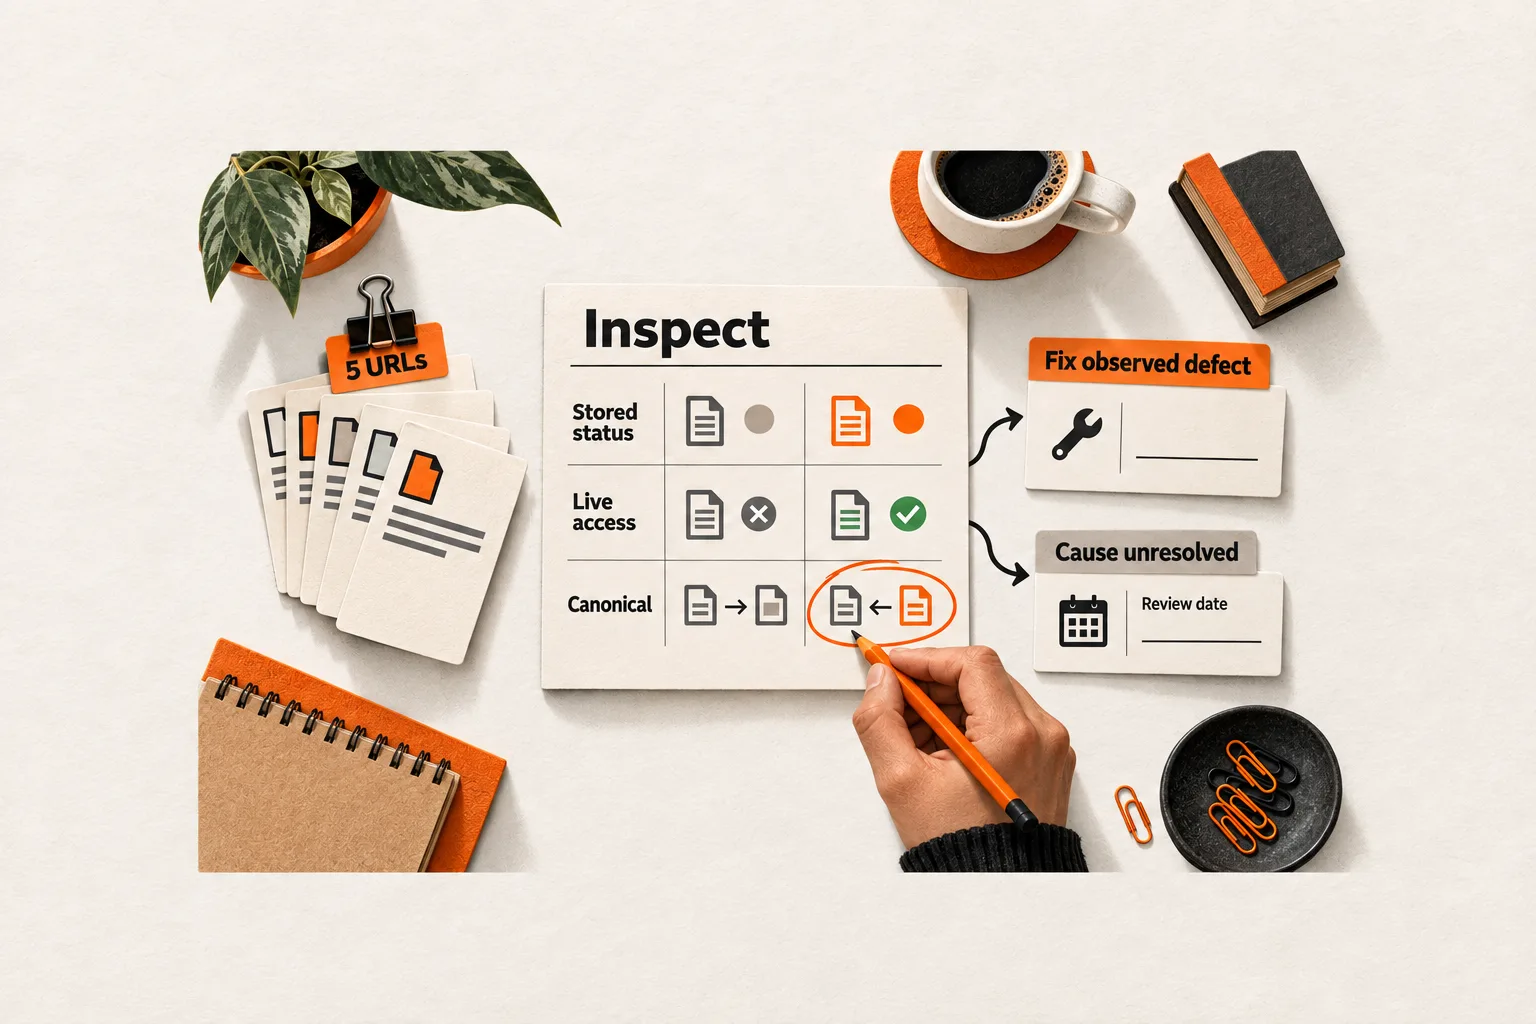
If your SaaS pages appear in a sitemap but remain “Discovered - currently not indexed,” start by inspecting five important URLs. Record Google’s stored status, test current access, and compare URL signals before deciding what to change.
Your audit should leave each page with either an observed problem to address or a dated record showing that the cause remains unresolved. An accessible page awaiting crawling does not automatically need a rewrite.
Understand what the status establishes
Google defines “Discovered - currently not indexed” as a URL it knows about but has not crawled yet. Its documentation says crawling is typically postponed because Google expects it could overload the site; the last crawl date is therefore empty. “Crawled - currently not indexed” means Google has fetched the page but has not indexed it. Google’s Page indexing documentation
The discovered status alone does not establish that Google inspected this page’s copy and rejected it. It also does not diagnose a penalty or prove your server is currently overloaded.
A sitemap helps Google discover URLs, but inclusion does not guarantee crawling or indexing. Check that its entry is correct, then move on to the page itself. Repeatedly submitting the same entry will not explain the delay. Google’s sitemap guide
Choose a small sample with useful comparisons
Start with five to ten URLs you want prospective customers to find. This is a practical audit size, not a Google requirement. Include important feature and use-case pages, examples from affected templates, and an indexed page from the same template if one exists.
Record each page’s buyer question and publication or substantial update date. Separate new pages from older ones that have remained in the same state across several checks. Exclude login screens, internal tools, and duplicate variants from the list of pages you want indexed independently.
In URL Inspection, save the stored result before running a live test. The stored result describes Google’s recorded state; the live test examines the page now. A successful live test does not confirm indexing, predict Google’s canonical choice, or check every indexing condition. Google’s URL Inspection guide
Use the comparison to choose where to investigate. If one template is affected, inspect its shared settings. If unrelated page types are affected, examine shared hosting, access controls, and site structure. Neither pattern proves a cause.
Check internal links and current access
For each sampled URL, follow an internal link from a relevant product, feature, or use-case page. Confirm that it reaches the intended public destination. Note outdated paths, unnecessary redirects, and pages available only through the sitemap.
Google already knows these URLs exist. This check establishes whether buyers have a sensible route to them and whether your links point to the pages you intend.
Run the live inspection and record whether crawling is allowed, the fetch succeeds, and indexing is allowed. Examine the tested HTML and screenshot for the substantive page content. These are separate checks: a successful fetch alone does not answer all of them. URL Inspection field definitions
Investigate failed checks for unintended robots.txt restrictions, noindex directives, authentication, or firewall challenges. A page that opens in your signed-in browser may behave differently for an unauthenticated request. Record a noindex directive as an indexing restriction, separately from a crawl or fetch failure.
For intermittent failures, ask your developer or hosting provider to examine the affected paths and timestamps. Look for server errors, rate limiting, and slow responses. Google says server health affects crawl capacity, and 5xx errors and 429 responses can reduce crawling. Its crawl-budget guide covers large or frequently updated sites and sites with a large share of URLs in the discovered state. That scope makes the guidance relevant to some small sites, but the status alone does not establish a capacity problem. Google’s crawl budget documentation
Fix observed access problems first. Consider more hosting capacity only when the evidence points to a capacity constraint.
Make the preferred URL consistent
Compare the destination URL, sitemap entry, internal links, and declared canonical. The canonical identifies your preferred version of a page. Check that a shared template has not accidentally declared the homepage or another feature page as canonical for a distinct feature page.
Google treats redirects and canonical annotations as strong canonicalization signals; sitemap inclusion is weaker. It recommends consistent signals and internal links to the preferred URL. Those signals express your preference without guaranteeing Google’s choice. Google’s canonicalization guide
Write the intended canonical beside the actual declaration. Record Google’s selected canonical from the stored inspection result when available. Mark missing information as unavailable; a successful live test cannot fill that gap.
A bad canonical on an uncrawled page is worth fixing before Google processes it. It does not prove what caused the crawl delay.
For duplicate pages, decide which version should be the search destination. Keep distinct feature pages separate when they answer different buyer needs. Pointing all of them at one generic URL would conflict with that goal.
Decide whether each page needs its own destination
Once access and URL signals are sound, compare the affected pages side by side. Google identifies page quality and relevance among the factors affecting Googlebot’s crawl demand. This supports a usefulness review, but it does not reveal why a particular URL is waiting. Google’s explanation of crawl demand
Ask whether a buyer could decide if the feature fits their workflow after reading the page.
For example, an AI meeting assistant’s sales-handoff page might explain which information transfers, how a user reviews the output, and what happens when required information is missing. A recruiting page needs a different workflow explanation if it is to justify a separate destination. These are hypothetical content examples, not claims about a particular product.
Changing an industry name across otherwise identical paragraphs gives readers little reason to visit both pages. Add useful product detail, combine overlapping pages, or retain a page for visitors without prioritizing its independent search visibility.
Combining pages reduces maintenance but can remove a useful destination for a distinct buyer need. Decide from the content and product, rather than the unindexed-page count. FindVex’s guide to planning SaaS pages around buyer questions can help with that review.
Investigate domain history with specific evidence
If the domain had a previous owner, check Search Console’s Manual actions report. Google says it shows manual actions and their history. For a recently purchased site with preexisting violations, its instructions are to fix the reported issues and explain the acquisition in a reconsideration request. Google’s Manual actions guide
If the report shows no action, record exactly that. It does not rule out every indexing issue. Old screenshots or an unrelated former business also do not establish that the current domain is penalized.
Keep old redirects, unexpected URLs, and documented manual actions as separate findings. A domain migration is a substantial change; put it on the task list only if the investigation produces a specific reason for it.
Worked example: twelve unindexed feature pages
Suppose a small AI SaaS has twelve feature pages in the discovered state. Its homepage and two older feature pages are indexed. All twelve affected URLs appear in the sitemap. This is a hypothetical audit, with no claimed indexing result.
The founder samples four affected pages and one indexed comparison page. Live tests succeed. One affected page declares the homepage as canonical, two answer nearly the same buyer question, and another has no contextual link from the relevant product section.
| Observation | Next action | What remains unknown |
|---|---|---|
| A distinct feature page declares the homepage as canonical | Correct the declaration and check other pages using that template | Whether this defect contributed to the crawl delay |
| Two pages answer nearly the same buyer question | Compare their content and combine them only if they serve the same need | Whether consolidation will change crawling or indexing |
| A feature page lacks a contextual product link | Add a link where it helps buyers reach the feature explanation | Whether the link will affect Google’s crawl timing |
A worksheet entry for the first page could read:
URL: /features/sales-handoff/
Buyer question: Can I review meeting details before handing them to sales?
Stored status: Discovered - currently not indexed
Last crawl: Unavailable
Live test: Fetch succeeded; crawling and indexing allowed
Intended canonical: This feature URL
Declared canonical: Homepage
Google-selected canonical: Unavailable
Observed defect: Canonical declaration conflicts with the intended destination
Unresolved cause: Reason for the crawl delay
Action and owner: Developer corrects declaration and checks shared template
Next check: Verify deployed declaration, then record the stored status again
In a real audit, add the actual check and completion dates. If a later stored result says “Crawled - currently not indexed,” you have evidence that crawling occurred, while indexing remains unresolved. None of the example’s changes guarantees indexing.
Copy the worksheet and set a review date
Use one record per priority URL. Write “unavailable” where a field cannot be checked and “none observed” where a completed check finds no defect.
URL:
Buyer question:
Should appear independently in search? Yes / no, with reason:
Publication or substantial update date:
Stored status and check date:
Last crawl date:
Live test date:
Crawling allowed / fetch result / indexing allowed:
Substantive content present in tested HTML and screenshot:
Internal linking page and sitemap entry:
Intended canonical / declared canonical / Google-selected canonical:
Observed defect and supporting evidence:
Hypothesis still needing evidence:
Change, owner, and completion date:
Next review date and observed result:
After correcting a page, you can use Request Indexing in URL Inspection. Submission is a request, not confirmation that Google has indexed the page. Google’s URL Inspection instructions
Choose a review date, such as one week later, as a working interval rather than an indexing deadline. Record whether the URL remains discovered, has been crawled, is treated as a duplicate, or is indexed. Track search impressions and customer activity separately.
If all checks pass, record “no defect observed; crawl delay unresolved” and review again on the chosen date. Avoid assigning a fix to an unconfirmed cause.
Start with five important URLs today. Complete their records, assign an owner to each observed problem, and put the next review on your calendar.